Full-stack platformJul – Sep 2026Working application · runs locally
AI Recruitment Assistant
A hiring platform that turns CVs and job posts into structured data, then ranks applicants with an explainable hybrid score.

Overview
A full-stack AI recruitment platform that helps recruiters turn CVs and job descriptions into structured data, match candidates to roles, and understand why each candidate scores the way they do.
Two role-based experiences on one backend. HR creates and publishes jobs and triggers screening runs; candidates register, upload a PDF résumé and apply. Claude extracts structured requirements and résumé data, embeddings and rules produce a weighted score, and every run is stored with the weights it used.
- CV and job-description analysis
- Claude extracts structured résumé data and job requirements through a schema-bound tool call, validated with Pydantic.
- Hybrid candidate matching
- Score = 0.5 semantic similarity (OpenAI embeddings) + 0.3 skill match + 0.2 experience.
- Explainable results
- Each candidate gets strengths, gaps and suggested interview questions, and each run stores the weights it used.
- Grounded recruiter Q&A
- Chat answers from stored screening results, so a conversation never silently changes a ranking.
- Two roles, one backend
- HR creates jobs and runs screening; candidates upload a PDF résumé and apply. JWT auth with role guards.
Screens
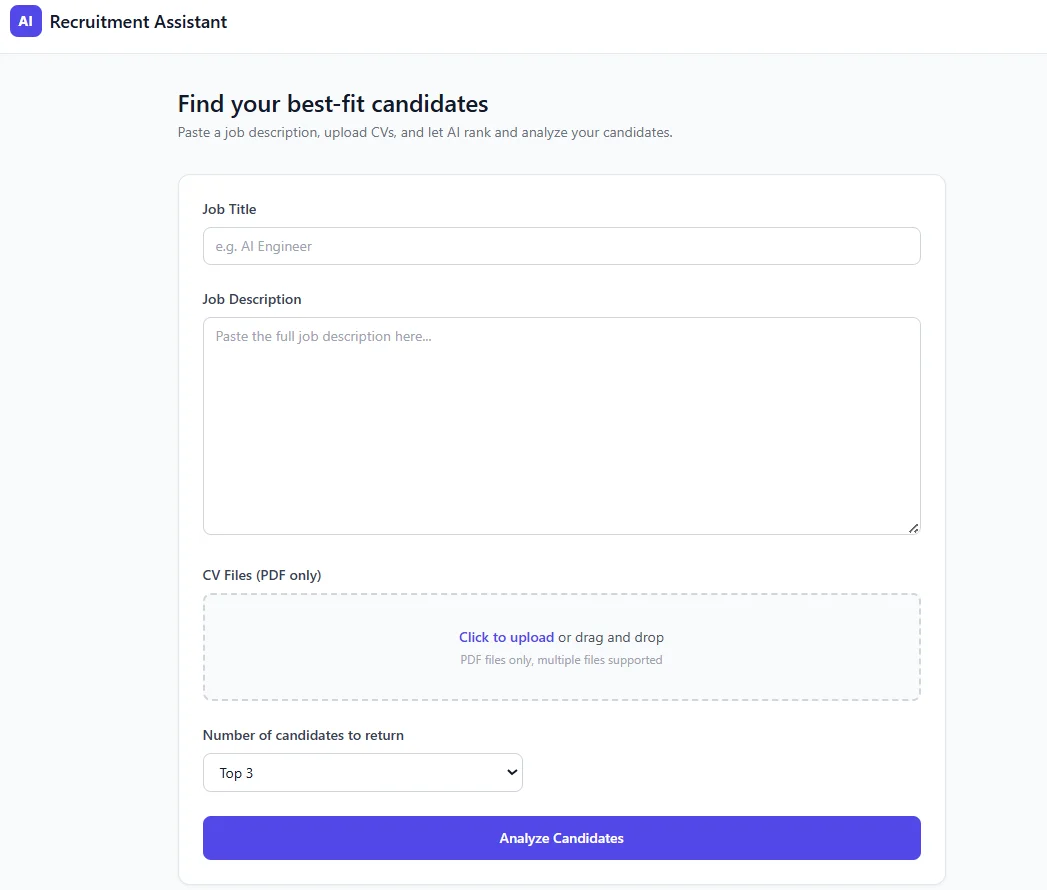
Start a screening run: paste a job description, upload PDF CVs, choose how many candidates to return. 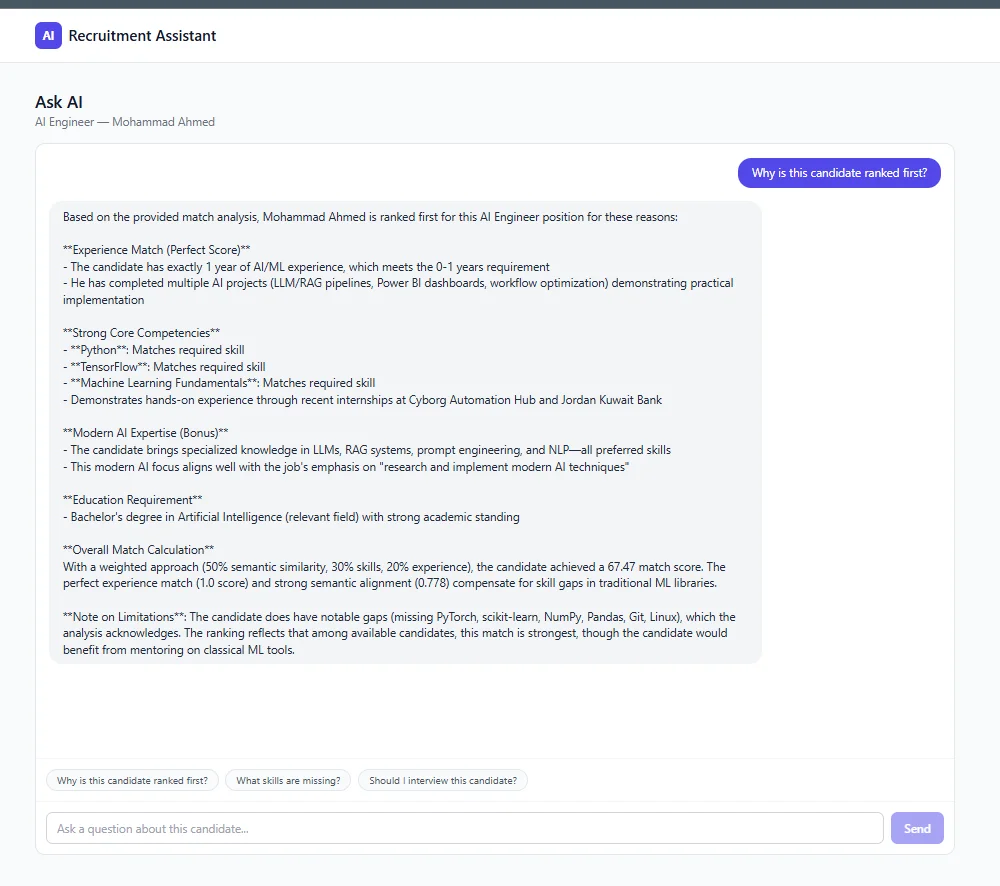
Per-candidate Q&A grounded in the stored screening result. 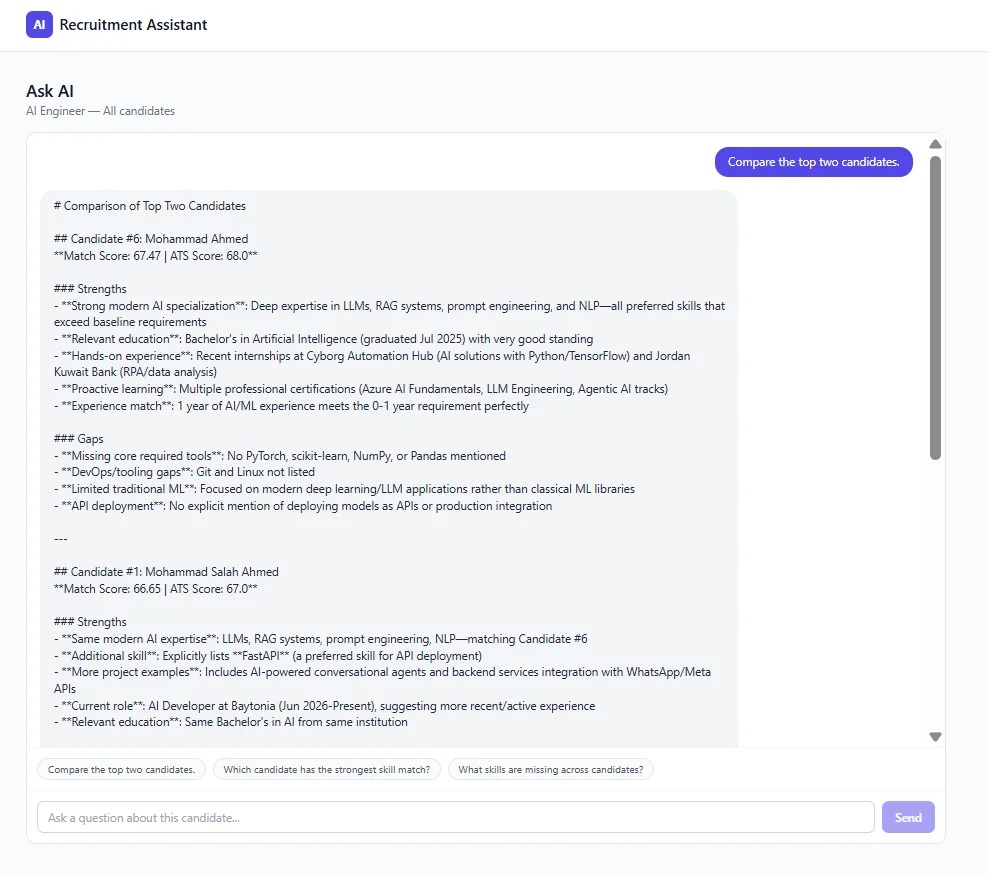
Comparing candidates across a run (sample run on test CVs).
Problem
First-pass CV screening is repetitive and inconsistent. A reviewer needs structured candidate data, a ranking they can explain, and a record of what each screening run actually did.
Architecture
- Next.js appApp Router + TypeScript. Auth context and role guards for HR and Candidate areas.
- FastAPI routersauth, jobs, profile, applications, screening, results, chat, health.
- Services layerLLM, résumé parsing, matching and screening logic kept out of the routers.
- PostgreSQL 16Async SQLAlchemy models with five Alembic migrations.
- Model providersClaude for extraction and analysis; OpenAI for embeddings only.
AI pipeline
- 1
Input
Job description text and a candidate's PDF résumé.
- 2
Preprocessing
PDF text extraction with pypdf.
- 3
LLM extraction
Claude is forced to call a schema'd tool; output is validated with Pydantic and retried if no tool call comes back.
- 4
Retrieval / scoring
Score = 0.5 semantic similarity + 0.3 skill match + 0.2 experience. Falls back to token overlap if embeddings fail.
- 5
Analysis
Per-candidate analysis, strengths, gaps and interview questions.
- 6
Output
A persisted screening run, with the weights it used, that HR can reopen and question.
- Claude forced tool-use for schema-bound extraction
- OpenAI text-embedding-3-small similarity
- Hybrid scoring: semantic + skills + experience
- Grounded Q&A over stored screening results
Engineering
- Structured output, not parsed prose
- Extraction goes through a forced tool call with a JSON schema, then Pydantic validation, with a retry when the model returns no tool block. Downstream code never parses free text.
- Runs are auditable
- Each screening run snapshots its scoring weights and stores a success or failed status per candidate, so one bad résumé cannot sink a run and old results stay interpretable if the weights change.
- Graceful degradation
- If the embedding call fails, similarity falls back to a bag-of-words cosine instead of failing the whole screening.
- Tighter account model
- Public registration only ever creates a Candidate. HR accounts are provisioned through a CLI script.
- Chat explains, it doesn't re-rank
- The chat endpoint answers from stored results, so a conversation can never silently change a ranking.
Challenges
- Testing async SQLAlchemy with asyncpg: connections bind to an event loop, so the tests create a fresh engine per test.
- Docker Compose environment variables were being shadowed by the host shell, so the stack uses an APP_ prefix.
- The model occasionally returned no tool call, which led to the retry in the extraction path.
Results & next steps
Measured
- No quantitative evaluation has been run. Ranking quality, latency and extraction accuracy are not measured yet.
- The backend has roughly 1,300 lines of pytest coverage across auth, jobs, applications, profile, screening and the database layer.
Known limits and next steps
- Skill matching is a simple substring check, so short skill names can false-match.
- The scoring weights are hand-chosen, not validated against labelled data.
- Not deployed, and no public demo.
Stack
- Frontend
- Next.jsTypeScriptTailwind CSS
- Backend
- FastAPIPydantic v2JWTpytest
- AI
- Claude (extraction, analysis)OpenAI text-embedding-3-small
- Database
- PostgreSQL 16SQLAlchemy 2 (async)Alembic
- Infrastructure
- Docker Compose
Demo
No public demo for this one yet. The source repository has setup instructions.